

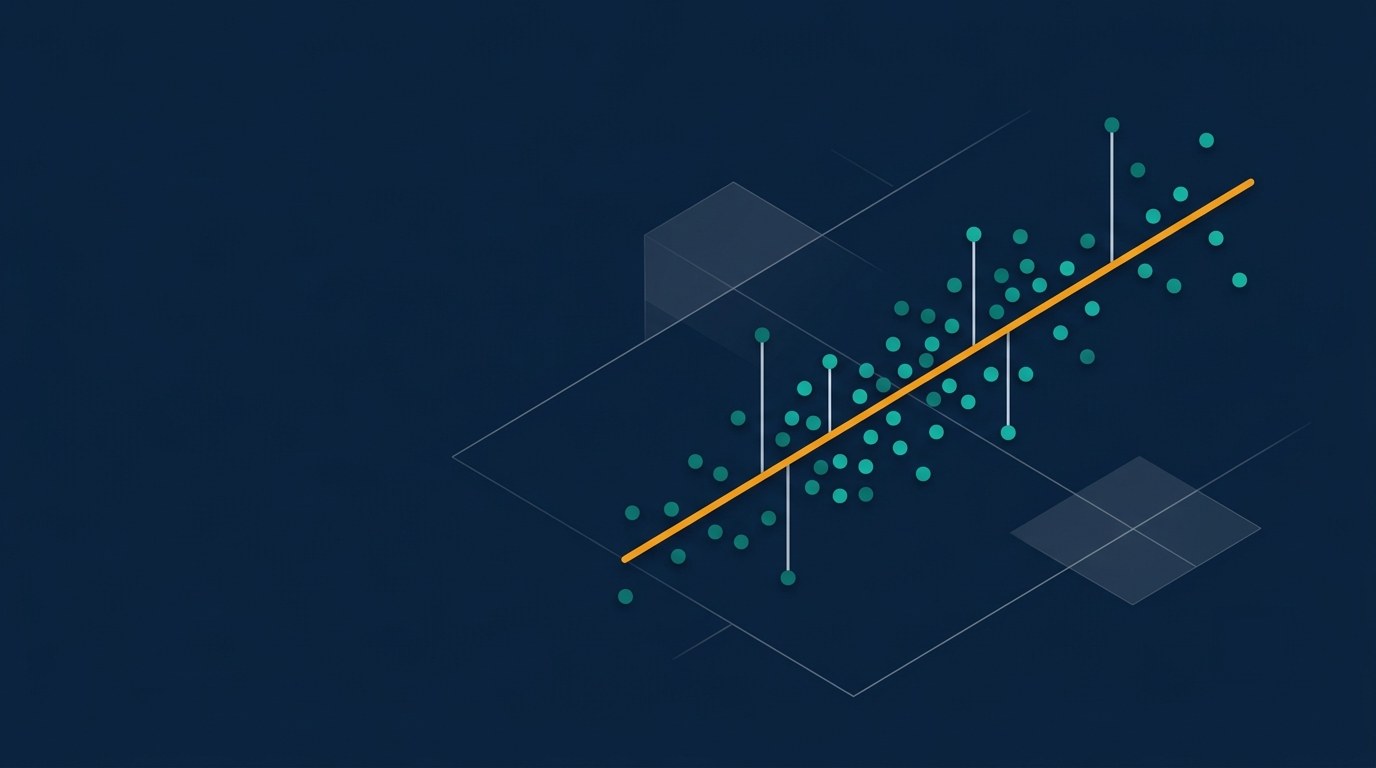
Have you ever wondered if you could predict the future with math not in a crystal ball, tea-leaves kind of way, but by connecting dots on a graph and saying, “Aha! I know what happens next”?
Can we estimate how long a cutting tool will last based on operating conditions? Can the selling price of a house be predicted by just knowing its size, age, and location? Is it possible to forecast a patient’s recovery time using their age, initial health condition, and medication dosage? How much fuel will a car consume given its engine size and weight? Can crop yield be predicted based on rainfall and fertilizer quantity?
Welcome to the surprisingly glamorous world of linear regression, where we use math, not magic, to forecast everything from tool wear to house prices.
These questions, which belong to different fields of expertise, could previously only be answered by experts of the field from which the questions are from. Now days all we have to do is make a simple or multiple linear regression model, where the data can be represented by various columns and rows.
The columns are the features, and the rows are the data, but there is a catch now: this is a predictive and supervised model. It will predict based on the data it has learned from the training data.
Tell Me Your Features and I’ll Predict Your Life
Let’s say you’re a grizzled machine operator. You notice that your cutting tools wear out faster when you crank up the spindle speed. Makes sense, right?
Now imagine you charted all those observations, and they formed a line (or close enough). Boom! You’ve just invented a simple linear regression model. The faster the spindle, the more the tool wears. No surprise just science.
But here’s the magic trick: if you know enough of these “spindle speed vs wear” data points, you can predict wear for any speed. Welcome to predictive modeling.
Linear regression tries to answer:
“How does the output variable change when the input variable(s) change?”
What’s a Supervised Learning Model?
A supervised learning model is like that strict math teacher who checks your homework. You give it examples, rows of data showing features (inputs) and what the result should be (output), and it learns the pattern.
Give it enough practice, and it’ll start making predictions like a seasoned pro. You just show it:
| Speed (RPM) | Feed Rate | Material Hardness | Tool Wear (mm) |
|---|---|---|---|
| 1500 | 0.25 | 500 | 0.15 |
And it says, “Okay, I get it. Let’s predict what wear looks like when RPM is 1700.”
Lets start with simple linear regression
The Legendary Equation of a Line (With a Twist)

this is a eqation of a stright line in general maths now for linear regression 


 – Predicted Value (Dependent Variable)
- This is the output you are trying to predict.
- In real life, this could be:
- Tool wear in a manufacturing process
- House price in real estate
- Fuel consumption in an automobile
 – Input Feature (Independent Variable)
- This is the input value or feature used to make the prediction.
- It’s called independent because it can be set freely and isn’t affected by y.
- Example:
- Spindle speed
- Size of a house
- Engine displacement
 – Slope of the Line
- The slope tells you how much yyy changes when x increases by 1 unit.
- Mathematically, it’s the rate of change.
- If m=2 , it means that for every increase of 1 unit in x, the predicted y increases by 2 units.
- It shows the strength and direction of the relationship:
- Positive mmm: upward trend (as x increases, y increases)
- Negative mmm: downward trend
 – Intercept
- The intercept is the value of y when x=0.
- It’s the point where the line crosses the y-axis on a graph.
- Think of it as the starting point or baseline output when there’s no input applied.
- Example:
- If no spindle speed is applied, the initial wear (might be due to setup) is bbb.

Now here’s the twist:
You can change the intercept (

Enters in The Ordinary Least Squares (OLS) — the method linear regression uses to find the best-fit line.
OLS works by choosing the line that minimizes the total squared distance between the actual values and the predicted ones. These distances are called residuals, and squaring them ensures we don’t cancel out errors (and also punishes big errors more).
Evaluation Metrics
RSS – Residual Sum of Squares
RSS measures the total squared difference between the actual values and the predicted values from the regression model.
Lets start with,

Where, 

With the equation of the regression line 

With the Ordinary Least Squares Method


Lower RSS means the model predictions are closer to actual values (i.e., better fit).
TSS – Total Sum of Squares
TSS measures the total variation in the actual data relative to the mean of the data.

considering [10, 12, 15, 18, 20] as an exapmle y values

Thus TSS would be

That’s the total variation in the data. How much the actual values deviate from the mean.

R² – Coefficient of Determination
R² tells us how much of the total variation (TSS) is explained by the model (via RSS). A key metric in regression that measures how well your model explains the variability in the data.

What does R² tell you?
| R² Value | Interpretation |
|---|---|
| 1.0 | Perfect fit – model explains 100% of the variability |
| 0.8 | Model explains 80% of the variability |
| 0.5 | Model explains 50%, the rest is error |
| 0.0 | Model explains nothing; it’s as bad as predicting the mean |
| < 0.0 | Worse than just predicting the mean (possible with bad models) |
Suppose the average house price is $300,000 (this is 

| Metric | Meaning |
|---|---|
| TSS | Total variation in the data |
| RSS | Remaining variation not explained by the model |
| R² | Fraction of the variation that is explained by the model |
Visual and numerical comparison of two regression models using R² (Coefficient of Determination)

Model Comparison
| Model | R² Score | Interpretation |
|---|---|---|
| Model A (orange line) | 0.994 | Excellent fit: ~99.4% of the variance in actual values is explained by this model. |
| Model B (red line) | 0.914 | Good, but not as strong: ~91.4% of the variance is explained. More error, less precision. |
Let’s take a deep look into the metrics that define the linear regression. We have a few more to go through
RSE – Residual Standard Error
This is an average estimate of how far the predictions are from the actual values the model is predicting. The measure of the typical size of the residuals. RSE gives you an estimate of the standard deviation of the residuals. It answers:
“On average, how far are the predicted values from the actual values?”

Where:
- RSS = Residual Sum of Squares
- n = number of observations
- k = number of predictors (independent variables)
Lower RSE → better model fit (predictions are closer to actual data points).
RSE vs R²
| Metric | What it measures | High value means | Units |
|---|---|---|---|
| RSE | Average prediction error | Bad model | Same as dependent variable |
| R² | % of variance explained | Good model | Unitless (0–1) |
MAE – Mean Absolute Error
| Aspect | Description |
|---|---|
| Formula |  |
| Meaning | Average of the absolute differences between actual and predicted values. Tells how far off predictions are, on average. |
| When to Use | – You need a robust metric not overly influenced by outliers. – You want easy-to-interpret results in original units. |
| Units | Same as the target variable y |
| Penalizes Large Errors? | ❌ No, treats all errors equally. |
| Notes | – Robust to outliers. – Simple to understand. – Not differentiable at zero, which can affect some ML optimizers. |
MSE – Mean Squared Error
| Aspect | Description |
|---|---|
| Formula |  |
| Meaning | Average of the squared differences between actual and predicted values. Amplifies large errors. |
| When to Use | – You want to penalize large errors significantly. – You’re using gradient-based optimization in ML. |
| Units | Squared units of y |
| Penalizes Large Errors? | ✅ Yes, heavily. |
| Notes | – Sensitive to outliers. – Differentiable, ideal for many machine learning algorithms. – Less interpretable due to squared units. |
RMSE – Root Mean Squared Error
| Aspect | Description |
|---|---|
| Formula |  |
| Meaning | Square root of MSE. Represents the standard deviation of prediction errors. |
| When to Use | – You want to penalize large errors, but still want interpretability. – When comparing model performance. |
| Units | Same as the target variable y |
| Penalizes Large Errors? | ✅ Yes, but less aggressively than MSE. |
| Notes | – Easier to interpret than MSE. – Balances error size with units. – Still sensitive to outliers. |
RSE – Residual Standard Error
| Aspect | Description |
|---|---|
| Formula |  Where,  |
| Meaning | Standard deviation of the residuals (errors) in the model. Adjusts for model complexity. |
| When to Use | – When evaluating linear regression models. – When considering number of predictors used. |
| Units | Same as the target variable y |
| Penalizes Large Errors? | ✅ Yes, includes squared residuals. |
| Notes | – Useful in statistical diagnostics. – Accounts for degrees of freedom. – Smaller RSE = better fit. |

Let’s have an example for finding out the MAE, MSE, RMSE, and RSE
Error Table
| X | Actual (y) | Predicted (ŷ) | Error (y – ŷ) | |Error| | Error² |
|---|---|---|---|---|---|
| 1 | 3 | 2.8 | 0.2 | 0.2 | 0.04 |
| 2 | 5 | 4.9 | 0.1 | 0.1 | 0.01 |
| 3 | 7 | 7.1 | -0.1 | 0.1 | 0.01 |
| 4 | 9 | 8.8 | 0.2 | 0.2 | 0.04 |
| 5 | 11 | 11.5 | -0.5 | 0.5 | 0.25 |
| 6 | 13 | 12.7 | 0.3 | 0.3 | 0.09 |
Error Metrics
| Metric | Value | Meaning |
|---|---|---|
| MAE | 0.233 | Average of absolute errors |
| MSE | 0.073 | Average of squared errors |
| RMSE | 0.271 | Square root of MSE, standard deviation of errors |
| RSE | 0.332 | Residual standard error (adjusted for predictors) |
Assumptions of Linear Regression
Before we go deeper. We have to look into the assumptions we make for a linear regression model in statistics.
A linear regression model finds the best estimiate of Y at every X. thus there is a distribution of error at every X. which are the differences between the observed values of the dependent variable (

How does the model predict a single value then?
Linear regression makes several key assumptions to ensure that the model provides accurate and reliable results. Here are the main assumptions:
- Linearity:
- There is a linear relationship between the dependent variable (Y) and the independent variable(s) (X). This means the change in Y is proportional to the change in X.
- Independence:
- The observations (data points) are independent of each other. This assumption is particularly important when dealing with time series or clustered data, where the values may be correlated.
- Homoscedasticity:
- The variance of the errors (residuals) is constant across all levels of the independent variable(s). This means that the spread of the residuals should be roughly the same for all values of X.
- Normality of Errors:
- The residuals (errors) of the regression model are normally distributed. This assumption is important for hypothesis testing and confidence intervals.
- No or Little Multicollinearity:
- If multiple independent variables are used, they should not be highly correlated with each other. High multicollinearity can make it difficult to isolate the effect of each variable on the dependent variable.
- No Autocorrelation:
- The residuals should not show patterns or correlations over time. Autocorrelation is particularly important in time series data, where residuals can often show dependencies.
If these assumptions are violated, the regression model may not be reliable, and alternative methods or transformations of the data may be necessary.
Residual
The residuals represent the “errors” or the unexplained variation in the data after fitting the linear model. The behavior and distribution of these residuals are important for validating the assumptions of the linear regression model.
Error Distribution in Linear Regression
Key Characteristics of the Error Distribution in Linear Regression:
- Normal Distribution:
- Assumption: The residuals (errors) should ideally be normally distributed. This means that most of the errors are small, with fewer large errors, following the shape of a bell curve (Gaussian distribution).
- Importance: The assumption of normality of errors is crucial for conducting hypothesis tests (such as t-tests for individual coefficients) and for constructing confidence intervals. If the errors are not normally distributed, the statistical significance of the model could be misleading.
- Mean of Zero:
- The residuals should have a mean of zero. This implies that the model is neither consistently overpredicting nor underpredicting the dependent variable on average.
- Constant Variance (Homoscedasticity):
- The variance of the residuals should be constant across all levels of the independent variables. This is known as homoscedasticity. If the residuals’ variance changes (i.e., they become more spread out or compressed as the value of X changes), this is called heteroscedasticity, and it violates one of the assumptions of linear regression.
- No Autocorrelation:
- The residuals should not be correlated with one another. If residuals at one point in time or position are correlated with residuals at another point, it indicates autocorrelation, which can invalidate the standard error estimates and affect hypothesis tests.
Why the Error Distribution Matters:
- Normality: Ensures that you can perform valid hypothesis testing, such as testing the significance of regression coefficients and constructing confidence intervals for predictions.
- Homoscedasticity: Ensures that the model is equally reliable for all levels of the independent variable(s). If heteroscedasticity is present, weighted least squares regression or a transformation of the data might be needed.
- Independence: Ensures that there is no systematic pattern in the residuals, which would suggest that important variables or relationships were left out of the model.
In practice, you can check the error distribution using:
- Residual plots: To check for homoscedasticity and identify patterns in the residuals.
- Histogram or Q-Q plot: To check if the residuals follow a normal distribution.
- Durbin-Watson test: To check for autocorrelation in residuals.
If the error distribution does not meet these assumptions, the results of the linear regression model may not be valid, and you may need to consider alternative models or corrective actions.

Lets Predict Advertising Spending
Let’s model Sales using TV advertising spend as the only predictor. Fitting the data using OLS Model (Ordinary Least Squares)
| Dep. Variable: | Sales | R-squared: | 0.816 |
|---|---|---|---|
| Model: | OLS | Adj. R-squared: | 0.814 |
| Method: | Least Squares | F-statistic: | 611.2 |
| Date: | Fri, 11 Oct 2024 | Prob (F-statistic): | 1.52e-52 |
| Time: | 19:25:47 | Log-Likelihood: | -321.12 |
| No. Observations: | 140 | AIC: | 646.2 |
| Df Residuals: | 138 | BIC: | 652.1 |
| Df Model: | 1 | ||
| Covariance Type: | nonrobust |
| coef | std err | t | P>|t| | [0.025 | 0.975] | |
|---|---|---|---|---|---|---|
| const | 6.9487 | 0.385 | 18.068 | 0.000 | 6.188 | 7.709 |
| TV | 0.0545 | 0.002 | 24.722 | 0.000 | 0.050 | 0.059 |
| Omnibus: | 0.027 | Durbin-Watson: | 2.196 |
|---|---|---|---|
| Prob(Omnibus): | 0.987 | Jarque-Bera (JB): | 0.150 |
| Skew: | -0.006 | Prob(JB): | 0.928 |
| Kurtosis: | 2.840 | Cond. No. | 328. |
Here’s what the results mean:
Model Summary
| Item | Meaning |
|---|---|
| Dependent Variable: Sales | This is what you’re trying to predict. |
| Model Type: OLS (Ordinary Least Squares) | Standard linear regression. |
| No. of Observations: 140 | Total data points. |
| Predictor Used: TV advertising spend | One independent variable. |
Model Fit & Performance
| Metric | Value | Meaning |
|---|---|---|
| R-squared | 0.816 | The model explains 81.6% of the variation in Sales. A strong fit for a single-variable model. |
| Adjusted R-squared | 0.814 | Adjusted for the number of predictors — still excellent. |
| F-statistic | 611.2 | The model is statistically better than a model with no predictors. |
| Prob (F-statistic) | 1.52e-52 | Extremely small → your model is highly significant. |
Coefficients (Effect of TV on Sales)
| Coefficient | Value | Meaning |
|---|---|---|
| Intercept (const) | 6.95 | If TV spending is 0, average sales would still be about 6.95 units. |
| TV Coefficient | 0.0545 | Every 1 unit increase in TV spend increases sales by about 0.0545 units. |
✅ Both values are statistically significant (P < 0.05), so they matter.
Residual Diagnostics
| Test | Result | Interpretation |
|---|---|---|
| Omnibus / Prob(JB) | Very high p-values | Residuals are normally distributed ✅ |
| Skew / Kurtosis | ~0 / ~3 | Residuals are symmetrical and normal ✅ |
| Durbin-Watson | 2.196 | No autocorrelation in residuals ✅ |
| Condition Number | 328 | No signs of multicollinearity ✅ |
Final Takeaway
- This is a strong, well-behaved model.
- TV advertising has a clear, positive, statistically significant effect on sales.
- The model satisfies all key regression assumptions.
💡 You can confidently use this model to predict sales based on TV ad spending.
Linear regression Models
1. OLS (Ordinary Least Squares) – Your current model
- Use case: Predicts a continuous output using a linear relationship.
- Equation:
- Goal: Minimize the sum of squared differences between actual and predicted values (RSS).

2. Ridge Regression
- Adds L2 regularization (penalty on the size of coefficients).
- Use case: When you have multicollinearity or want to prevent overfitting.
- Shrinks coefficients but doesn’t remove any.
3. Lasso Regression
- Adds L1 regularization, which can shrink some coefficients to zero.
- Use case: Feature selection + regularization.
- Helps in sparse models.
4. Elastic Net Regression
- Mix of Ridge and Lasso (L1 + L2).
- Use case: When you want the benefits of both regularization types.
5. Generalized Linear Models (GLM)
- Extends linear regression to models like:
- Logistic Regression: For binary classification.
- Poisson Regression: For count data.
- Allows the response variable to follow different distributions (not just normal).
6. Robust Linear Models
- Handles outliers better than OLS.
- Use Huber loss or quantile regression to reduce influence of outliers.
✅ Summary: Which Model Type to Use?
| Model Type | Best When… |
|---|---|
| OLS | Data is clean, linear, and assumptions are met. |
| Ridge | You have many predictors and want to reduce multicollinearity. |
| Lasso | You want to automatically eliminate less important predictors. |
| Elastic Net | You want regularization + feature selection. |
| Robust | Your data has outliers. |
| GLM | Your outcome is not continuous (e.g., binary, count). |
Conclusion
Linear regression is the OG of predictive modeling. It’s like fitting a ruler through chaos and pretending life is simple. Whether you’re a machine shop veteran, a budding data scientist, or just someone who likes drawing straight lines, regression gives you power.
Power to predict. Power to understand. And most importantly, the power to look smart in front of your manager.
Still wondering how linear regression goes from “just a line” to “look, it predicts stuff!”? Hop on and ride through my BoomBikes project where weather, seasons, and people’s habits collide to forecast bike demand — with Python doing the pedaling.pedalling
🚲 GitHub repo with all the nerdy goodness is here — don’t worry, no helmet required!
One response to “Linear Regression Explained: A Beginner’s Guide to Prediction”
[…] Linear Regression Explained: A Beginner’s Guide to Prediction […]